
AI agents can now research, route enquiries, update CRMs and trigger workflows—but a successful pilot is not the same as a dependable production system. For UK and UAE teams, the practical question is no longer simply “Does the agent work?” It is “Can we see what it did, explain why, catch failures quickly and improve it safely?”
This guide turns AI agent observability into a lightweight operating scorecard that SMEs can use across customer service, sales operations, finance, HR and internal knowledge workflows.
What AI agent observability means
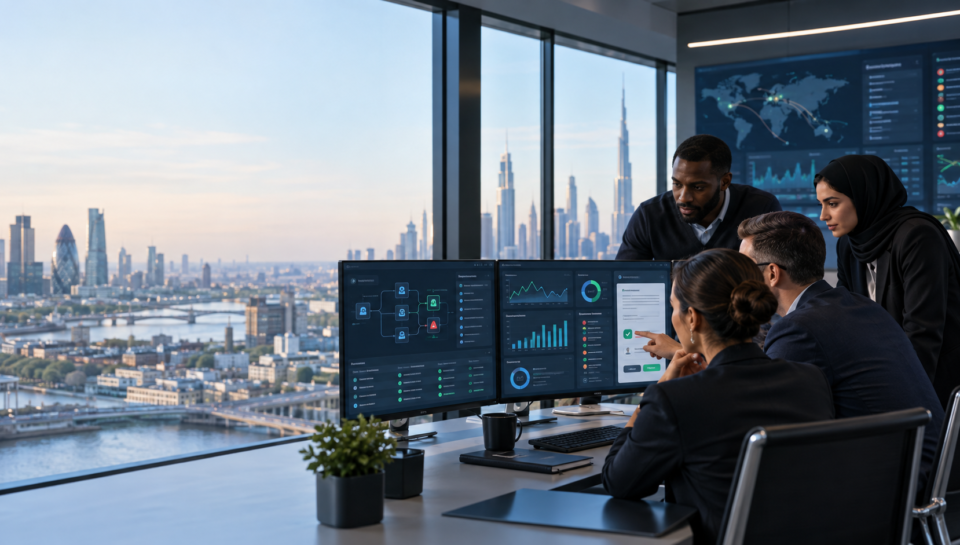
Traditional application monitoring asks whether a service is online, fast and error-free. An AI agent needs those checks plus visibility into the quality and safety of its decisions. It may choose tools, call external systems, retrieve documents, generate text and hand work to people. Observability connects those steps into a trace that a responsible owner can review.
A useful setup records the user request, the agent’s plan, data sources consulted, tools called, approvals requested, output delivered, latency, cost and final outcome. Logs should be useful without becoming a new store of unnecessary personal or confidential data.
Why UK and UAE businesses need a scorecard
The UK government’s guidance on using AI in services stresses accuracy, transparency, security, human contact and continuous monitoring. The UK’s AI assurance guidance frames assurance as evidence that a system meets relevant criteria.
In the UAE, the Charter for the Development and Use of Artificial Intelligence highlights transparency, human oversight, governance and accountability. These principles translate naturally into measurable operating controls.
NIST’s AI Risk Management Framework groups practical work into govern, map, measure and manage. Its guidance says AI systems should be tested before deployment and regularly in operation, with post-deployment monitoring, user feedback, override and incident-response mechanisms.
The eight-part AI agent observability scorecard
1. Task success rate
Define success in business terms, not simply whether the model produced an answer. A lead-routing agent succeeds when the lead reaches the correct owner with the required fields. A support agent succeeds when the customer receives an accurate resolution or a clean human handover.
- Track completed, partially completed and failed tasks.
- Separate model failures from integration, permissions and data-quality failures.
- Review results by workflow, customer segment and language.
2. Grounding and source quality
Measure whether outputs are supported by approved, current sources. For knowledge agents, log which documents or records were retrieved and whether the answer can be traced back to them. Flag responses that use stale policies, missing citations or sources outside the approved knowledge base.
3. Tool-call reliability
Agents often fail at the boundary between reasoning and action. Monitor successful calls, timeouts, retries, permission errors and malformed data for every connected CRM, inbox, database and automation platform. A dashboard should reveal whether one integration is creating most exceptions.
4. Human escalation quality
A safe handover is a feature, not a failure. Track how often the agent escalates, whether it escalates at the right moment, the context passed to the reviewer and the time required for resolution. High-risk actions—payments, contractual commitments, hiring decisions or publishing—should have an explicit approval gate.
5. Safety and policy compliance
Create a small test set for prohibited actions, sensitive-data handling, prompt injection and misleading outputs. Run it before each major change and sample live interactions. Record breaches, near misses and the control that prevented or failed to prevent the issue. Our AI agent governance checklist provides a companion framework for permissions and oversight.
6. User experience
Monitor response time, abandonment, repeat questions, handover satisfaction and correction requests. Quantitative data should be paired with short user feedback. A technically correct agent can still fail if it is confusing, inaccessible or slow.
7. Cost and resource efficiency
Track model usage, tool costs and human-review time per successful task. Compare the automated process with the previous baseline. Optimise expensive prompts and repeated calls, but never trade away accuracy or appropriate review simply to reduce token spend.
8. Change and incident readiness
Every agent needs an owner, version history, rollback path and incident plan. Record model, prompt, knowledge-base and integration changes. When performance shifts, the team should be able to identify what changed and restore the last trusted configuration.
A practical weekly dashboard
| Metric | Example signal | Owner action |
|---|---|---|
| Task success | Successful outcomes by workflow | Review the three largest failure groups |
| Grounding | Unsupported or stale-source answers | Refresh content and tighten retrieval rules |
| Actions | Tool errors and retries | Fix the weakest integration |
| Escalation | Incorrect or late handovers | Adjust thresholds and context |
| Experience | Abandonment and corrections | Improve prompts, UI and accessibility |
How to implement AI agent observability in 30 days
- Week 1: map the workflow. List inputs, decisions, data sources, tool calls, human checkpoints and desired outcomes.
- Week 2: instrument the critical path. Add trace IDs, structured events, error categories and outcome labels. Redact or minimise sensitive data.
- Week 3: build the scorecard. Start with five to eight metrics, set a baseline and agree thresholds for review or shutdown.
- Week 4: run an operating review. Sample real traces, test failure scenarios, assign improvements and record decisions.
For connected systems, pair this approach with secure no-code integration governance so logs, credentials and exception queues remain controlled.
Common mistakes to avoid
- Collecting everything: more logs can increase privacy and security risk. Capture what supports operations, assurance and incident response.
- Watching only uptime: a healthy API can still produce poor business outcomes.
- Using one average: segment results to expose failures in specific languages, workflows or customer groups.
- No action owner: every red metric needs a named person and response window.
- Changing too much at once: version prompts, models, tools and content so improvements remain explainable.
Frequently asked questions
Do SMEs need a specialist observability platform?
Not necessarily. Many teams can begin with structured workflow logs, a spreadsheet or BI dashboard, and a weekly review. Specialist tooling becomes valuable as the number of agents, integrations and transactions grows.
What should never appear in an agent trace?
Avoid unnecessary passwords, access tokens, payment details, identity documents and full conversation content containing personal data. Use masking, retention limits and role-based access.
How often should an AI agent be evaluated?
Continuously for operational errors, weekly or monthly for outcome trends, and before and after material changes to models, prompts, data sources or integrations.
Build an agent you can trust in production
Creative & Co. helps UK and UAE businesses design AI agents, workflow controls, dashboards and human approval paths that are practical to operate—not just impressive in a demo.